Published June 15, 2024
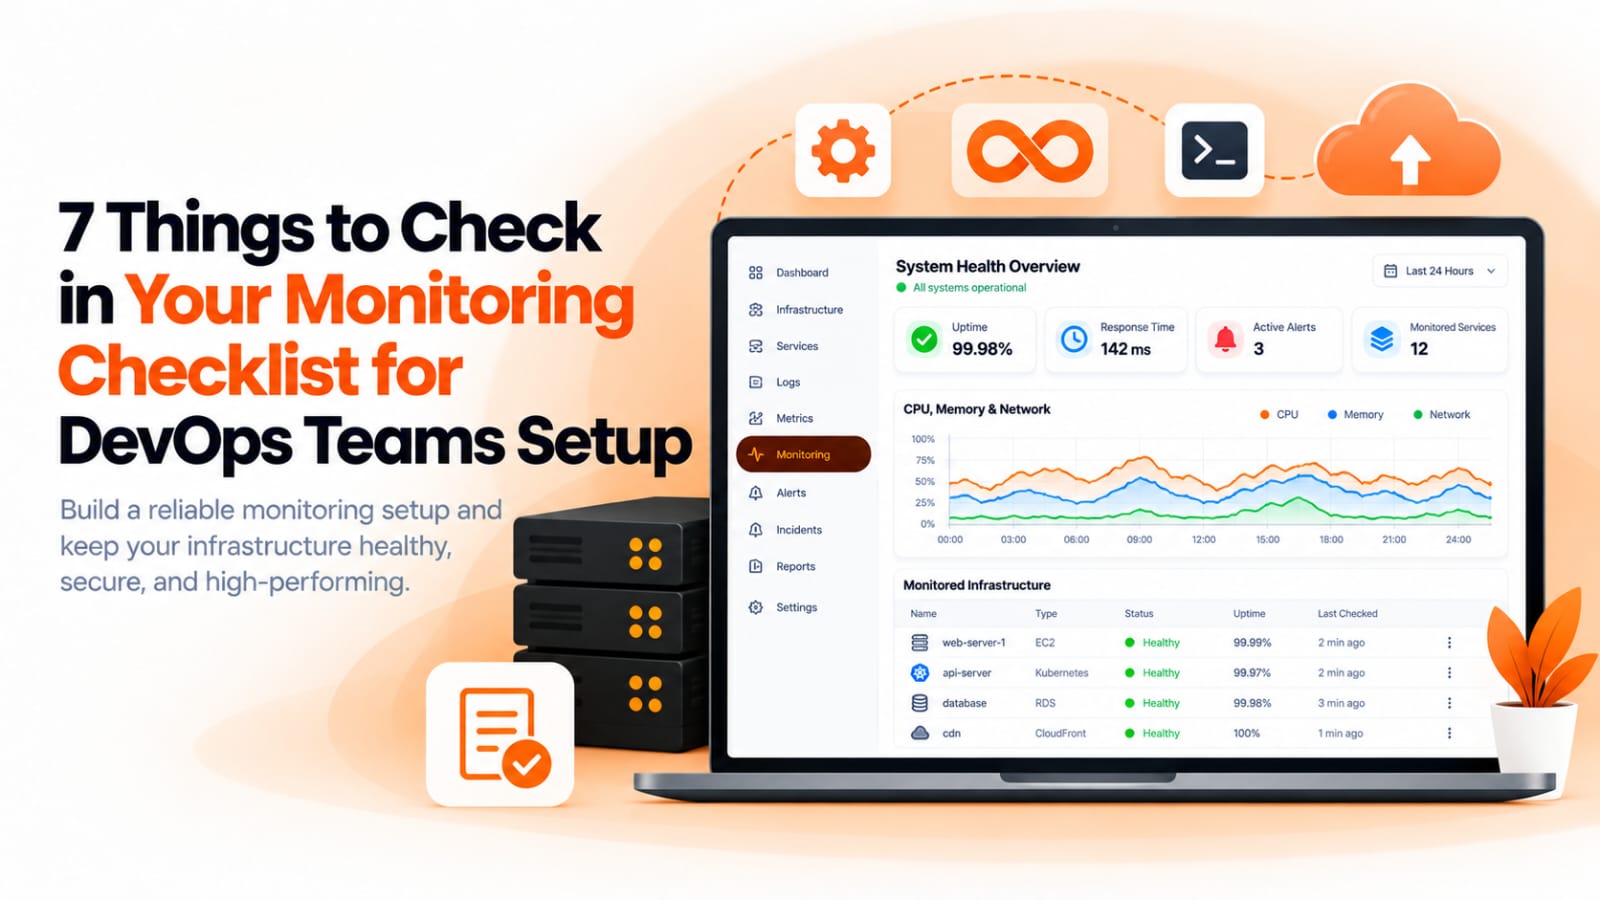
Most monitoring setups don't get designed all at once — they get built one incident at a time. A server runs out of memory, so someone adds a CPU check. A certificate expires, so someone adds an SSL alert. A few years in, the result is a patchwork that covers whatever already broke, with no guarantee it covers what's about to. A proper devops monitoring checklist is what catches that gap before the next incident finds it.
This list runs through seven things worth confirming in your current setup, whether you're building one from scratch or auditing what you already have.
It's easy to watch the main production box closely and forget the smaller ones — a worker, a staging server, a cron host — until one of them runs out of resources and takes something down with it. Resource usage needs to be tracked continuously across the whole fleet, not just the servers that feel important, so a slow leak shows up in the data long before it becomes an outage.
A cloud virtual machine already has real performance data available through the provider it runs on. Pulling that data directly, rather than estimating it separately, is what makes monitoring across a multi-cloud setup consistent instead of patchy.
A server can look healthy internally while the service running on it is unreachable from the outside, due to a firewall rule or a crashed process. Checking from outside, the way a real user would reach it, catches what an internal-only view misses.
Certificate expiry is one of the most predictable outages there is, and it still catches teams off guard because nothing else about the server changes until the exact moment it happens. It deserves its own check, separate from general uptime.
A CPU or memory threshold that works for a database server will either fire constantly or stay silent on a lightly used staging box. Thresholds set against how each resource actually behaves are what make alerts worth acting on.
A brief spike shouldn't wake anyone up, but a sustained one should reach whoever can actually fix it — not a shared inbox nobody watches. And once something's fixed, a recovery notification should confirm it, so nobody's left manually checking.
An open port, a database missing deletion protection, a server with no backup configured — these accumulate quietly across a growing infrastructure footprint and often go unnoticed until an audit, or worse. Catching them automatically, rather than relying on someone to remember to check, is what actually keeps them from piling up.
Not every monitoring tool covers all seven of these out of the box, so it's worth checking before committing to one. Start with the basics: does it track resource usage continuously across every server, and does it pull cloud VM metrics directly from the provider rather than approximating them?
From there, look at how it handles noise and ownership. A tool that lets you set thresholds per resource, add a delay before alerting, and route alerts to a specific team rather than one shared destination will hold up much better as your infrastructure grows and more teams start depending on it. Finally, check whether security and configuration issues are surfaced automatically, or whether you'd need a separate tool just to catch those.
BigBell's monitoring covers this checklist directly. A lightweight agent tracks CPU, memory, and disk usage on any Linux server, and for cloud virtual machines, BigBell pulls performance data straight from AWS CloudWatch, Azure Monitor, or Google Cloud Monitoring, depending on where each one runs. BigBell's URL monitoring checks uptime and response time from outside your infrastructure, and SSL certificate expiry is tracked on its own independent schedule.
Thresholds are set per server or application rather than one blanket default, and a configurable delay keeps a brief spike from becoming an unnecessary alert, while a recovery notification goes out once things are healthy again. Alerts can be routed at the organization, project, or application level, reaching your team through email, Slack, Microsoft Teams, Google Chat, WhatsApp, SMS, or a phone call. Automated insights also scan connected accounts for common security and configuration gaps, including open sensitive ports, missing termination or deletion protection, and resources without backups configured.
Try BigBell free and run this checklist against your own infrastructure.
Starting with resource usage and uptime checks covers the most common early failures. The rest — SSL expiry, tuned thresholds, alert delay and routing, and security checks — are worth adding as the setup matures, rather than skipping entirely.
Whenever infrastructure changes meaningfully — a new server added, a new cloud provider brought in, traffic patterns shifting — rather than only once at initial setup. A checklist built once and never revisited tends to age into exactly the kind of gap it was meant to prevent.
Because the provider's own monitoring service already has accurate, real-time data for that VM. Pulling it directly avoids duplicating collection and keeps the numbers consistent with what you'd see in the provider's own console.
No, it means fewer false alarms. The delay only holds off on alerting for genuinely brief blips — a sustained issue still triggers an alert quickly, just without paging someone over a five-second spike.
Resource monitoring tells you how a server is performing right now. A security or configuration check flags a setup risk — like an open port or a missing backup — that might not cause a problem today but will eventually.
Yes. Alerts can be routed at the organization, project, or application level, so a database issue and a general server alert don't have to reach the same people, and each team only sees what's actually relevant to them.
Both. A recovery notification goes out once a server or service returns to a healthy state, so nobody has to keep manually checking whether an issue is actually resolved.
Not if alerting is set up properly. The point of a delay and clear routing is that the team doesn't need to actively watch a dashboard — a problem only surfaces when there actually is one, and it reaches the person who can act on it.